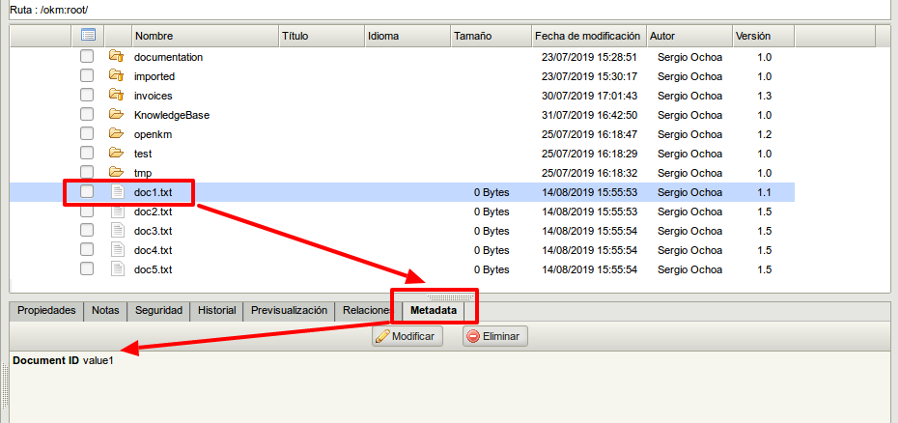
Script - Import data from CSV file
The script can be executed from the administration scripting (or used as an automation script too) to import metadata values.
The CSV file has two columns; the first column contains the document path and the second column has the metadata value.
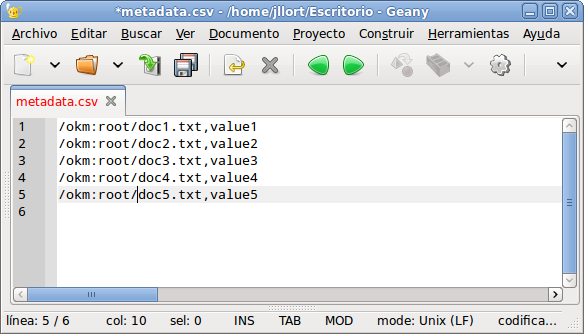
Download the CSV sample file csv_metadata.zip.
The metadata group definition:
<?xml version="1.0" encoding="UTF-8"?><!DOCTYPE property-groups PUBLIC "-//OpenKM//DTD Property Groups 3.10//EN""http://www.openkm.com/dtd/property-groups-3.10.dtd"><property-groups> <property-group label="Metadata" name="okg:metadata"> <input label="Document ID" name="okp:metadata.value" type="text"/> </property-group></property-groups>The script:
import java.io.FileReader;import java.io.Reader;import java.util.Collection;import java.util.HashMap;import java.util.Iterator;import java.util.List;import java.util.Map;
import com.googlecode.jcsv.CSVStrategy;import com.googlecode.jcsv.reader.CSVReader;import com.googlecode.jcsv.reader.internal.CSVReaderBuilder;import com.googlecode.jcsv.reader.internal.DefaultCSVEntryParser;import com.openkm.api.OKMDocument;import com.openkm.api.OKMPropertyGroup;import com.openkm.api.OKMSearch;import com.openkm.bean.Document;import com.openkm.bean.QueryResult;import com.openkm.db.bean.QueryParams;import com.openkm.util.ContextWrapper;import com.openkm.util.PathUtils;
String grpName = "okg:metadata";String FILE_LOG_NAME = "CSVLOG";String META_PATH = "/home/openkm/csv/";String META_FILE_NAME = "metadata.csv";int uniqueFileName = 0;int valueColumn = 1;
// Format defintionchar delimiter = ',';char quoteCharacter = '"';char commentIndicator = '#';boolean skipHeader = false;boolean ignoreEmptyLines = true;CSVStrategy strategy = new CSVStrategy(delimiter, quoteCharacter, commentIndicator, skipHeader, ignoreEmptyLines);// File readerReader reader = new FileReader(META_PATH + META_FILE_NAME);// CSV readerCSVReader csvParser = new CSVReaderBuilder(reader).strategy(strategy).entryParser(new DefaultCSVEntryParser()).build();List data = csvParser.readAll();int count = 0;int countFound = 0;int countNotDocument = 0;int moreThanOneDocumentFound = 0;int notFound = 0;int noName = 0;
OKMSearch okmSearch = ContextWrapper.getContext().getBean(OKMSearch.class);OKMPropertyGroup okmPropertyGroup = ContextWrapper.getContext().getBean(OKMPropertyGroup.class);PathUtils pathUtils = ContextWrapper.getContext().getBean(PathUtils.class);
for (int i = 0; i < data.size(); i++) {    String[] row = (String[]) data.get(i);    String docPath = row[uniqueFileName];    print(count + ">>>> " + docPath);
    if (docPath != null && !docPath.equals("")) {        QueryParams queryParams = new QueryParams();        queryParams.setDomain(QueryParams.DOCUMENT);        queryParams.setName(pathUtils.getName(docPath));        Collection results = okmSearch.find(null, queryParams);
        if (results.size() == 1) {            QueryResult queryResult = (QueryResult) results.iterator().next();            if (queryResult.getNode() != null && queryResult.getNode() instanceof Document) {                print("found");                countFound++;
                Map properties = new HashMap();                properties.put("okp:metadata.value", row[valueColumn]);
                // Add Group and metadata                okmPropertyGroup.addGroup(null, docPath, grpName, properties);            } else {                print("error is not document");                countNotDocument++;            }        } else if (results.size() > 1) {            print("error more than one document found can not decide");            moreThanOneDocumentFound++;        } else {            print("not found");            notFound++;        }    } else {        print("error document has no name");        noName++;    }
    print("</br>");
    count++;}
print("Total:" + count + "</br>");print("Found:" + countFound + "</br>");print("Error not document:" + countNotDocument + "</br>");print("Error more then one document found:" + moreThanOneDocumentFound + "</br>");print("Error not found:" + notFound + "</br>");print("Error name empty:" + notFound + "</br>");Register the metadata group
Section titled “Register the metadata group”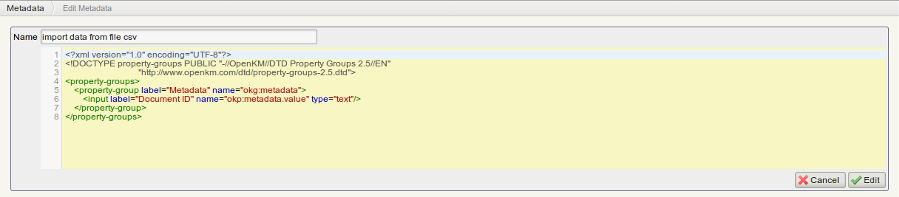
Repository view
Section titled “Repository view”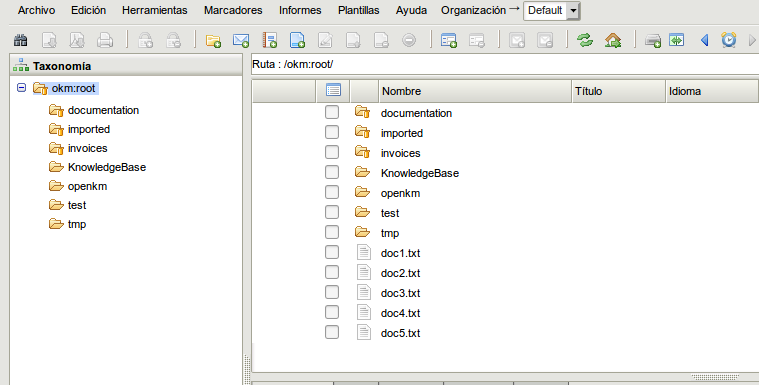
Execution
Section titled “Execution”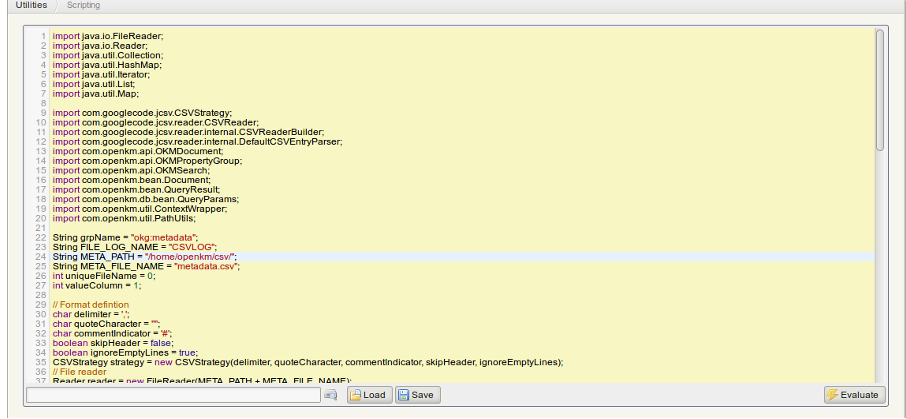
Script results
Section titled “Script results”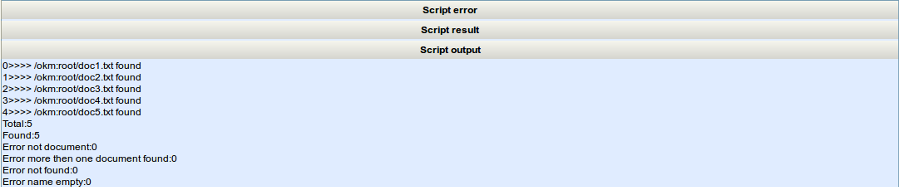
Imported metadata
Section titled “Imported metadata”